The science that matters.
Don't risk probabilistic LLMs deciding your next hire. Hubert is deterministic, safe and legally defensible by design.
Every interview feels human. Every response is scored fairly. The same output for the same input, with full visibility for the recruiter.
Book a demoTwo AI systems, doing two different jobs
Most AI hiring tools use a single large language model (LLM) to do everything: hold the conversation, interpret the response, generate a score, and write the explanation. This is not legally defensible.
Hubert separates the two jobs that should never share a model.
Interviews that feel human
This handles the interview with the candidate: asking follow-up questions, acknowledging answers, keeping the experience warm and natural across 30+ languages.
This is where generative AI earns its place, ensuring a structured interview feels human.
Scoring that is safe and trusted
This scores responses using proprietary, deterministic models grounded in the STAR framework and Behaviorally-Anchored Rating Scales. The scoring logic is explicit, the weights fixed, and the explanation is the exact logic that produced the score, not a narrative generated after the fact.
With Hubert the conversation feels human. The scoring is auditable. You do not have to choose between the two.
Deterministic models: the safe, legally defensible option
Both approaches can deliver shortlists. Only one gives the same answer for the same input every time to make a safe shortlist for human decision-making.
Trained on more than one million expert human evaluations
Hubert's assessment models are not trained on whatever the internet had to offer. They are trained on more than one million manual evaluations conducted by experienced human raters using Behaviorally-Anchored Rating Scales, the structured interviewing standard widley recognized as the most equitable method in organizational psychology research (Schmidt & Hunter, 1998).
- ✓Accuracy measured against expert human scoring, not against another artifical LLM
- ✓Validity grounded in years of structured interviewing science
- ✓Bias controls built into the training data, not bolted on at inference
Built and validated by experts
Hubert's scientific direction is led by Dr Fredrik Törn, Chief Product Officer. Dr Törn holds a Ph.D. from the Stockholm School of Economics, with deep expertise across assessment, leadership, people analytics, human behavior, AI, and product development. Every model release, validation study, and bias audit at Hubert is signed-off under his direction and alongside our candidate pledge.
Read the candidate pledge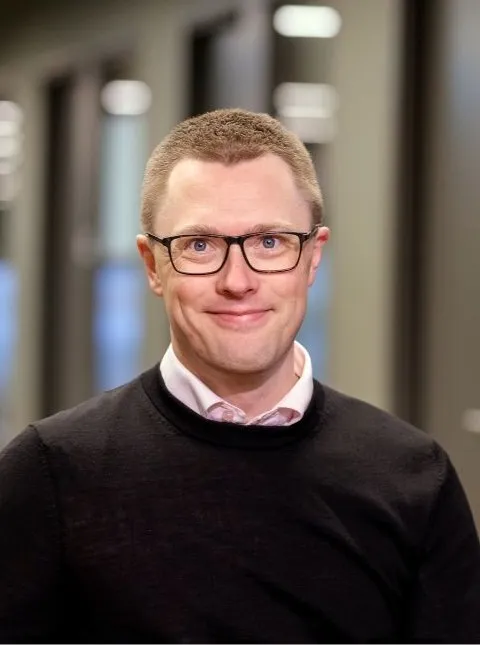
Interviews built around competencies that predict performance
Before a candidate is ever interviewed, Hubert's Recruiter Agent builds a structured skills-based interview template from the job description, translating the role into the competencies that actually predict on-the-job performance. The recruiter reviews and signs off.
Then every candidate for that role is assessed against the same competencies, with the same weights, by the same deterministic model version. That is what makes a shortlist comparable: a consistent set of questions, consistent evaluation criteria, and consistent scoring models.
Versioned. Validated. Locked.
A model that drifts is a model that produces different scores for the same answer on different days. For a hiring decision that has to hold-up in court, that is not a trade-off; it is a disqualification.
1
Every release is dated, documented, and traceable to the candidates it scored.
→
2
New versions are tested against expert human scoring before release.
→
3
The model does not change during a hiring cycle. Every candidate is assessed identically.
→
4
Continuous monitoring for drift and adverse impact, with transparent bias audits.
Six principles of Responsible AI
These are the six pillars Hubert's assessment models and products are designed against to ensure responsible AI in hiring in everything we do.
- ExplainabilityTransparent explanations for every AI score. No 'black-boxes'.
- QualityScientifically validated assessments that predict real-world performance.
- ConsistencySame input, same output. Deterministic scoring.
- SecurityData privacy and data minimization by design.
- FairnessEqual opportunity for all candidates, regardless of protected characteristics.
- Human oversightDecision remains firmly with the recruiter.
What deterministic models deliver in production
Loved by the teams who hire at scale.
“Hubert helps us deliver faster, fairer hiring for candidates and employers today — and builds the next, strengthening human potential through responsible technology.”
“We can finally explain every shortlisting decision. The scores are consistent, and that consistency is what makes them defensible.”
“Thousands of applicants screened within hours, fairly, every time. It changed what our team can take on.”
“Candidates get a real interview the moment they apply, and we get a shortlist we can actually trust.”
AI in recruitment is classified as high-risk.
That changes what you can ship.
Under the EU AI Act, AI used in recruitment is high-risk by default. Article 13 requires transparency sufficient for human interpretation of outputs. The supplier has to be able to explain, not narrate.
Probabilistic LLM scoring cannot meet that standard. Research has now demonstrated, repeatedly, that LLMs produce meaningfully different rankings for identical CV inputs across runs (Redstone 2025; Seshadri et al. 2025; Varshney & Ganuthula 2025). A candidate's career should not depend on which server processed their application.
Hubert was founded before the generative AI boom, and the deterministic assessment layer was the original product, not a retrofit. That is the foundation we build on to be fair, safe, and legally defensible.
EU AI Act ready
GDPR compliant
Human oversight by design
Deterministic scoring
Frequently asked questions
What is a deterministic AI model?+
Does Hubert use LLMs?+
How is a Hubert score explained?+
How often are the models updated?+
What is Hubert trained on?+
Who leads the science at Hubert?+
Is this EU AI Act compliant?+
See structured AI interviews in action
A 30-minute walkthrough with our team tailored to your roles, volumes and ATS.
No forms after this one. We reach out to schedule your walkthrough.